
ReLU (Rectified Linear Unit) is an activation function with formula:
$$ f(x) = \max(0, x) $$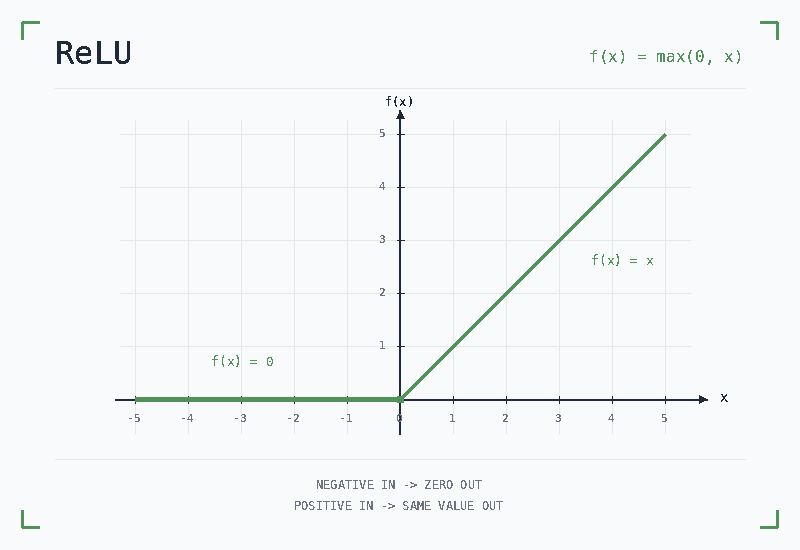
It is the default activation function in the hidden layers of modern neural networkss (FNN, CNN, etc.) and it just checks if a number is larger than zero, allowing for quick computation and fast convergence.
Pros:
- it tackles the vanishing gradient problem, keeping the gradient flow strong during backpropagation - this happens because its derivative (gradient) for any positive input is always exactly 1
- it allows sparse activation, meaning that only relevant neurons fire, while negative inputs are zeroed out
Cons:
- while it prevents gradients from vanishing for positive inputs, it introduces the so-called dying ReLU problem for negative inputs: for any input smaller than zero, the gradient is exactly 0. If a neuron gets pushed into negative values during training, it will output zero, receive a zero gradient, and permanently stop updating its weights. This is fixed using leaky ReLU.