
In statistics and machine learning, Bias refers to the error coming from model oversimplification and leading to underfitting.
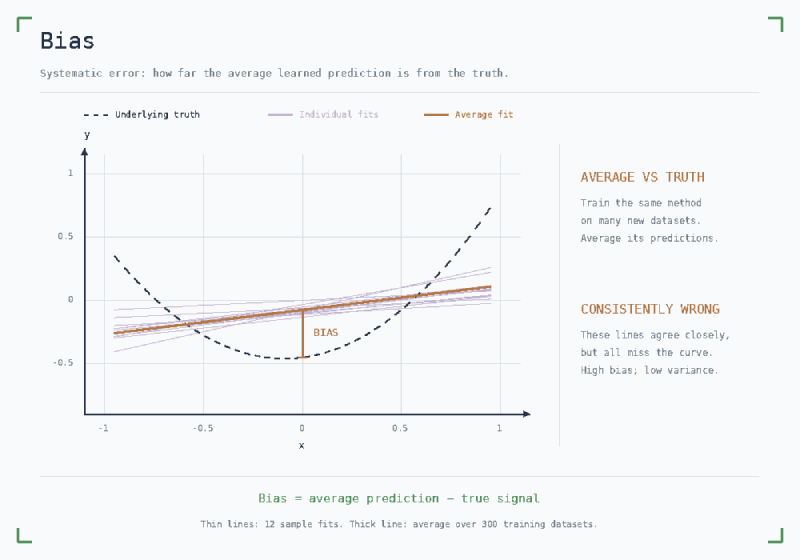
A model with high bias is not able to capture the true complexity of the data, leading to poor performance on both training set and test set.
The bias is represented by the difference between the expected or true value of the target variable and the predicted value of the model.
Together with variance, this is a fundamental concept to understand the bias-variance trade-off.